Introduction
MTBF, MTTR, MTTA, and MTTF are core reliability and incident-response metrics that tell you different parts of the same story: how often things fail, how fast you notice them, how quickly you restore service, and how long assets last before failing. The most important part is to measure them with clear event timestamps and a consistent definition of what counts as a failure, an acknowledgment, and a recovery.
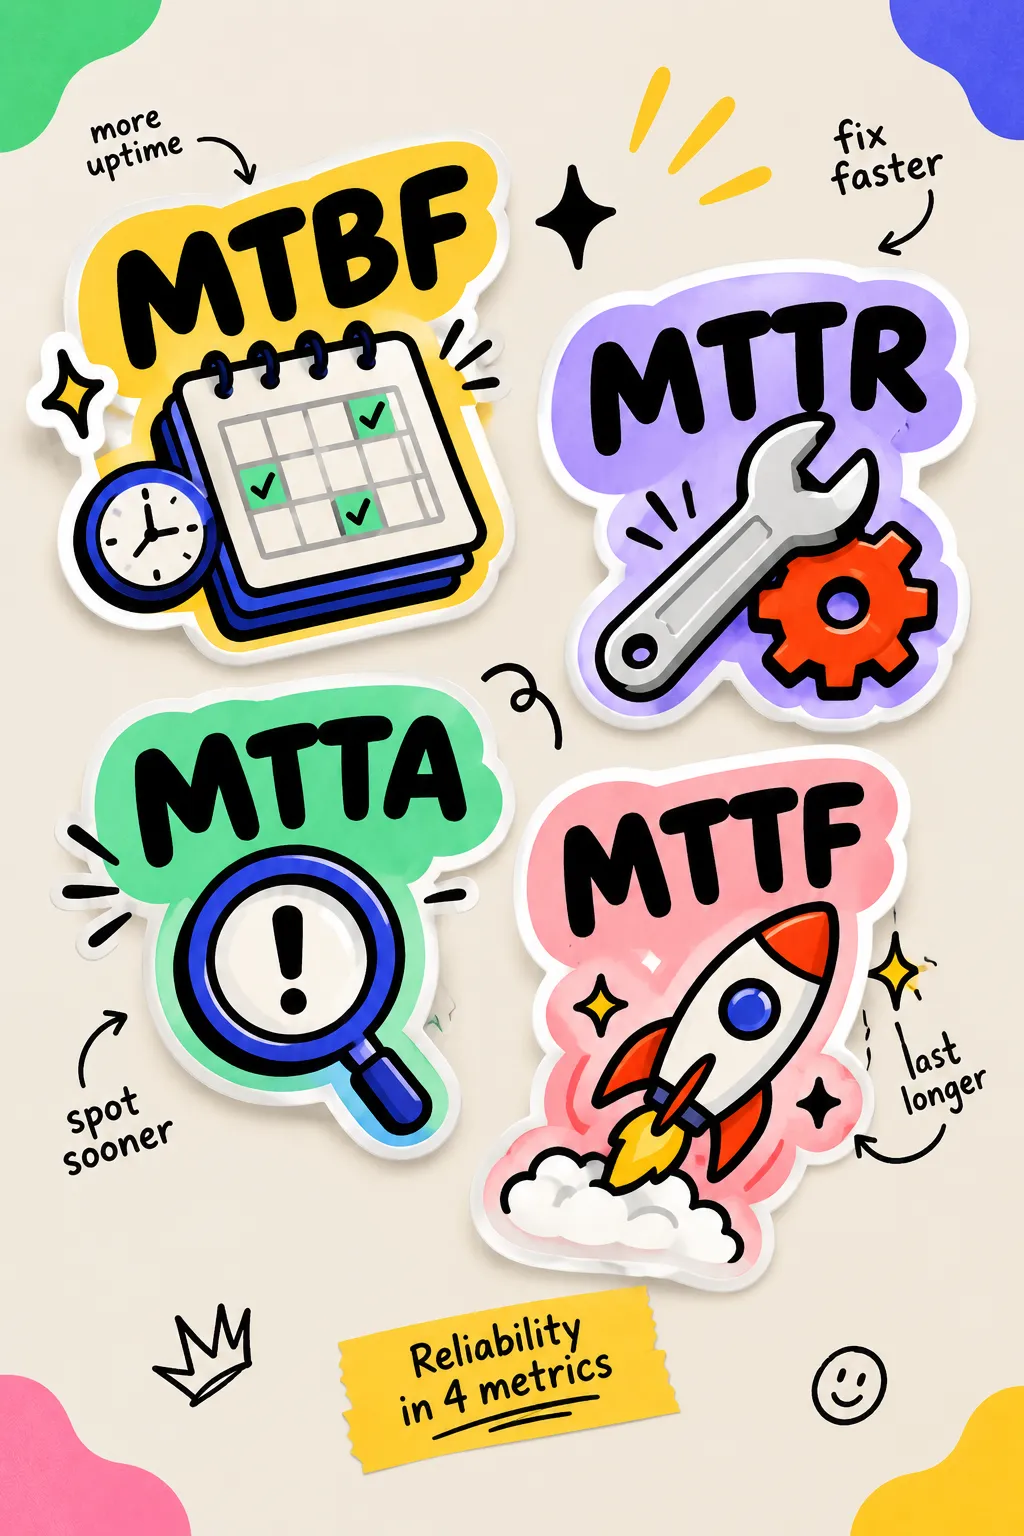
What each metric means
- MTBF (Mean Time Between Failures) Average operating time between one failure and the next for a repairable system.
- MTTR (Mean Time To Repair/Recover/Resolve) Average time needed to restore service after a failure.
- MTTA (Mean Time To Acknowledge) Average time from incident occurrence or alert creation until someone acknowledges it.
- MTTF (Mean Time To Failure) Average time until a non-repairable item fails; it is mainly used for assets that are replaced, not repaired.
Formulae
Where:
- is the total operating time
- is the number of failures
- is the total downtime
- is the number of incidents
- is the total time to acknowledge
A disclaimer about MTTR
When we talk about MTTR, it’s easy to assume it’s a single metric with a single meaning. But the truth is it potentially represents four different measurements. The R can stand for repair, recovery, respond, or resolve, and while the four metrics do overlap, they each have their own meaning and nuance.
So if your team is talking about tracking MTTR, it’s a good idea to clarify which MTTR they mean and how they’re defining it. Before you start tracking successes and failures, your team needs to be on the same page about exactly what you’re tracking and be sure everyone knows they’re talking about the same thing.